

turboagents
A Python package that compresses KV-cache and vector payloads for existing agent runtimes and retrieval pipelines, adding reranking and benchmarking without requiring a new framework.
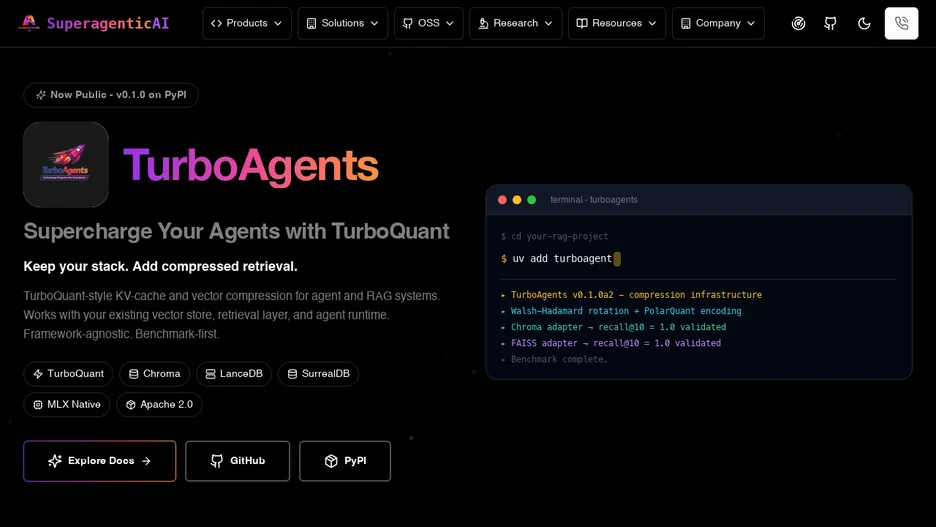
turboagents provides compression infrastructure that sits underneath existing agent frameworks, local inference stacks or RAG pipelines. It compresses KV-cache payloads so inference can hold more context, and compresses vector payloads so retrieval systems can store and rerank more cheaply, rather than replacing the framework itself.
Its quantization core combines a Fast Walsh-Hadamard rotation, a PolarQuant-style angle and radius stage, and a seeded QJL-style residual sketch to produce binary payloads. It ships wrappers for MLX and llama.cpp inference engines, adapters for Chroma, FAISS, LanceDB, SurrealDB and pgvector retrieval backends, and a benchmark suite that measures payload size, reconstruction quality and retrieval agreement.
It is packaged for uv-based local workflows and published to PyPI.