

UniversalRAG
A research framework for retrieval-augmented generation across text, image, video, and mixed-granularity corpora, using a learned or training-free router to pick the right corpus per query.
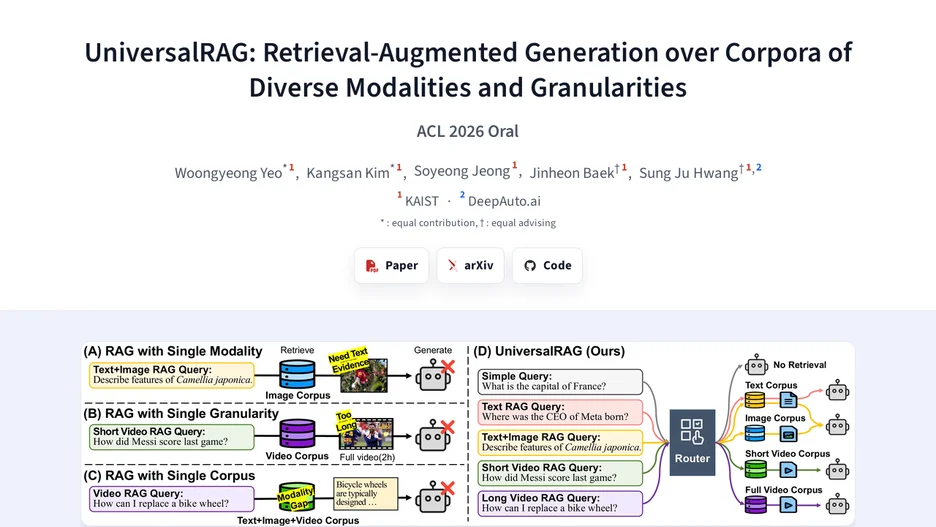
UniversalRAG is a retrieval-augmented generation framework, presented as an ACL 2026 paper, that retrieves across corpora of different modalities and granularities rather than assuming a single fixed one. A modality-aware routing mechanism dynamically identifies the most appropriate modality-specific corpus for each incoming query, addressing gaps between modalities and the limits of fixed-granularity retrieval used in typical RAG setups.
The released code covers preprocessing datasets and extracting embeddings for queries and corpora across modalities, training a router, such as a vision-language model or a smaller text model, or using a training-free router such as a general-purpose LLM, running inference with a chosen router, and evaluating the resulting routed retrieval against a target dataset with a vision-language model of choice. Dependencies are managed with uv, and multi-GPU preprocessing is controlled through a device list.