

Veridrop
An open-source tool that checks whether an AI API relay or proxy service genuinely forwards to the Claude, GPT or Gemini model it claims, by diffing probe requests against official API baselines.
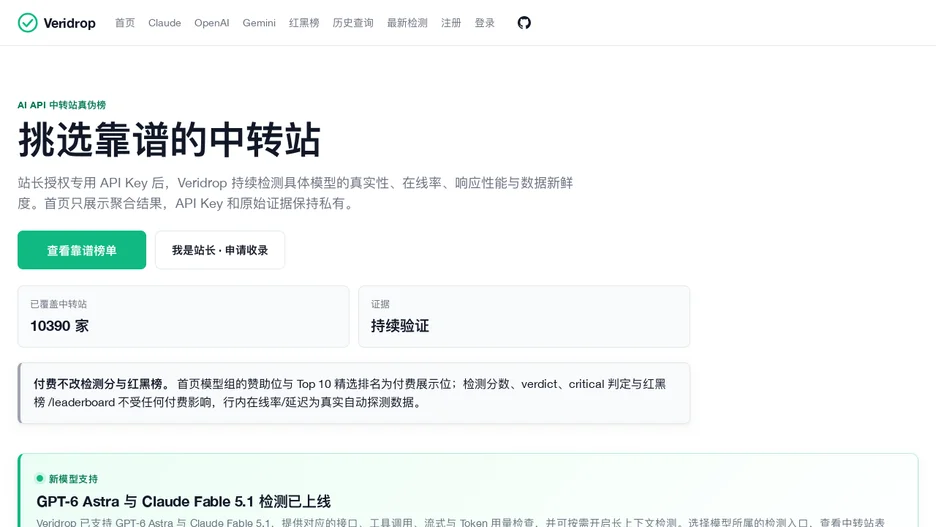
Veridrop is an authenticity and compliance checker for AI API relay and proxy services. Given a base URL, API key and model name, it runs a set of probe requests and compares the responses against official-API baselines at the field, protocol and cryptographic level, to answer three questions: whether the relay really forwards to the model it claims rather than a cheaper substitute, whether advanced features such as PDF input, tool use, extended thinking, function calling and long context are silently stripped, and whether response fields, streaming event sequences and usage accounting match the official API specifications.
It supports the Anthropic Messages API, the OpenAI Chat Completions API, and the Gemini OpenAI-compatible API. A hosted version runs the same checks without requiring signup and does not persist submitted API keys; the project reports that the community has run tens of thousands of public detections across thousands of relay providers, aggregated into a public leaderboard.
The tool can also be self-hosted, with its detection logic, scoring weights and evidence fields published in this repository under the AGPL-3.0 license.