

vllm-mlx
A vLLM-style inference server for Apple Silicon that adds continuous batching, paged and prefix KV caching, and both OpenAI and Anthropic-compatible APIs in one process.
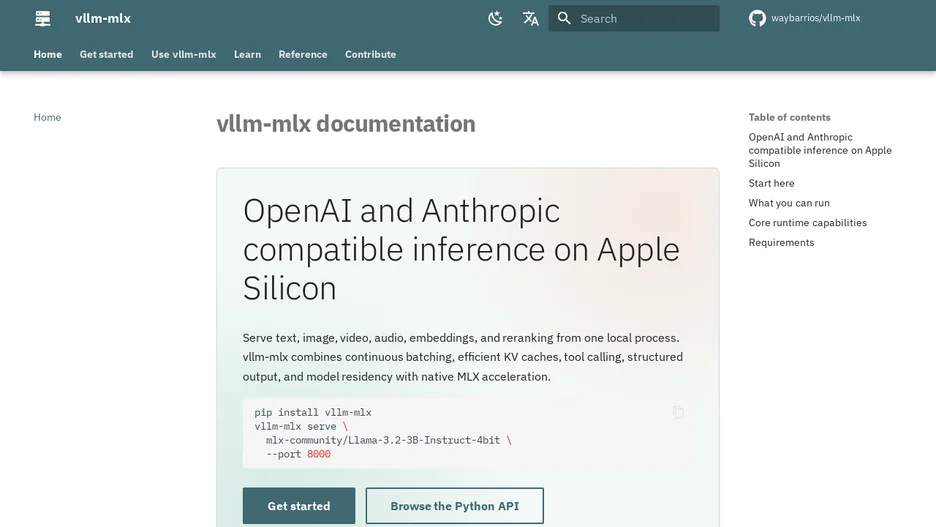
vllm-mlx is an inference server for Apple Silicon Macs that runs language, vision, audio and embedding models natively on Metal with unified memory and no conversion step. Unlike using Ollama or mlx-lm directly, it adds continuous batching, a paged key-value cache, prefix caching and an SSD-tiered cache, and it exposes both OpenAI's /v1 endpoints and Anthropic's /v1/messages endpoint from a single running process, so the same server works as a drop-in backend for either SDK or for Claude Code directly.
It installs from PyPI and is started from the command line with a chosen model; a validated compatibility matrix confirms it completes a streamed tool call and an exact file edit with several coding CLIs, including OpenCode, Pi, Codex, Claude Code, GitHub Copilot CLI, Cline and OpenClaw's embedded agent, against the same local model. It is written in Python and licensed under Apache 2.0, with documentation in English, Spanish, French and Chinese.