

vMLX
A self-hosted inference server for LLMs, vision-language models and image generation on Apple Silicon, exposing OpenAI, Anthropic and Ollama compatible HTTP APIs with no third-party API keys required.
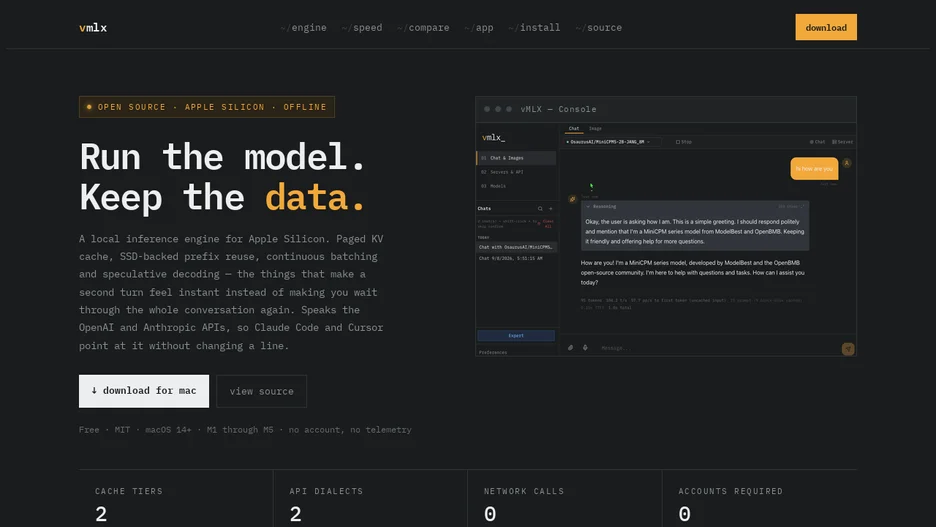
vMLX is a self-hosted inference server for Apple Silicon that serves language models, vision-language models and image generation models over OpenAI, Anthropic and Ollama compatible HTTP APIs. It applies native MTP artifact detection and family-specific cache policy gates to keep speculative-decoding and cache settings explicit and model-safe, and works with models from the mlx-community collection.
It installs from PyPI with a single command, or through a native macOS desktop app (MLX Studio) that adds a chat interface, model management, image generation and developer tools without a terminal. A companion quantization format, JANGQ, adapts precision per layer and is reported to improve accuracy over standard MLX quantization at a comparable model size.