

whatcanirun
A website and command-line tool for finding which large language models will run well on your own hardware, backed by community-submitted benchmark results.
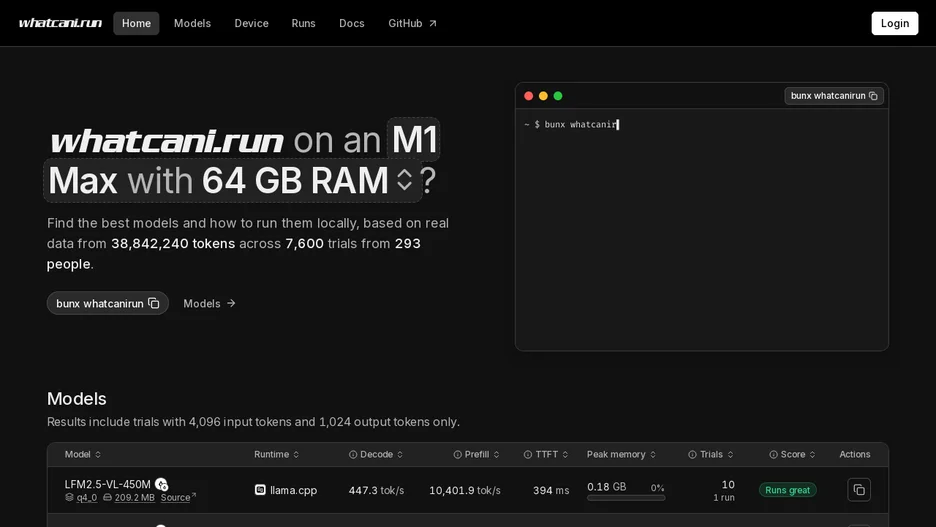
whatcanirun helps you find AI models that run locally on your own hardware and benchmark them. The whatcani.run website lets you browse models, filter by device, and view benchmark results submitted by the community, while the whatcanirun CLI, published on npm as wcir, runs standardized local LLM benchmarks on your machine and can submit the results back to the site.
The project is a monorepo built with Bun and Turborepo, split into a Next.js web app, the CLI benchmarking tool, and a shared package of types, schemas, and utilities. The CLI exposes run, show, and submit commands for running a benchmark, inspecting device or model information, and uploading a saved results bundle.